


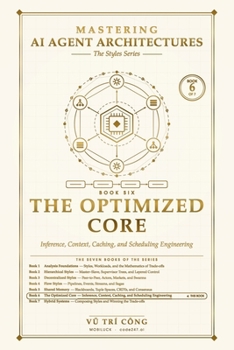
Mastering AI Agent Architectures: The Optimized Core: Inference, Context, Caching, and Scheduling Engineering (Mastering AI Agent Architectures — The Styles Series)
No Customer Reviews

Were the verdicts about price, or about architecture? This book finds out.
Books 2-5 found that almost every multi-agent style beats a single agent on accuracy and loses on cost. This book puts a tuned inference core under all 65 styles of the series and switches on, one at a time, the techniques inference engineering offers - then re-runs every style.
Cost anatomy: every bill split into calls, input tokens, output tokens and rolesPrompt and KV caching - about a fifth off with no answer changedSemantic caching - safe only when tight, and dangerous inside a pipelineBatching and offline batch APIs - a clock decisionModel cascades - the biggest lever, and why verifiers must never be cascadedContext compression with measured loss curvesDraft-verify execution, and why it needs a cache to be cheaperStragglers, hedging, placement and deadline-first schedulingThe tuned decision cards show which verdicts moved - monitoring and the 5 cap - and which did not, because they were structural all along.
Runnable code, frozen and tuned results under three locks at tag gauntlet-b6. Book 6 of 7 in Mastering AI Agent Architectures - The Styles Series.
Format:Paperback
Language:English
ISBN:B0HKHCLYNV
ISBN13:9798175727433
Release Date:September 2026
Publisher:Independently published
Length:213 Pages
Weight:0.65 lbs.
Dimensions:9.0" x 0.5" x 6.0"
Customer Reviews
0 rating
Copyright © 2026 Thriftbooks.com
Terms of Use | Privacy Policy | Do Not Sell/Share My Personal Information | Cookie Notice | Cookie Preferences | Accessibility Statement
ThriftBooks ® and the ThriftBooks ® logo are registered trademarks of Thrift Books Global, LLC
ThriftBooks ® and the ThriftBooks ® logo are registered trademarks of Thrift Books Global, LLC
