


All Formats & Editions
1 - 1 of 1 results found
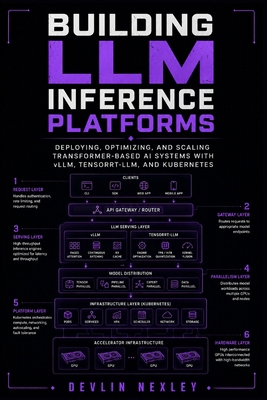
Building LLM Inference Platforms
Edition Description
Modern large language model (LLM) systems are no longer simple model deployments-they are high-performance distributed inference infrastructures operating under strict latency, throughput, and memory constraints. As organizations scale generative AI from prototypes...
Edition Details
Format:Paperback
Language:English
ISBN:2200177674
Format: Paperback
Condition:
$
25.00
Copyright © 2026 Thriftbooks.com
Terms of Use | Privacy Policy | Do Not Sell/Share My Personal Information | Cookie Notice | Cookie Preferences | Accessibility Statement
ThriftBooks ® and the ThriftBooks ® logo are registered trademarks of Thrift Books Global, LLC
ThriftBooks ® and the ThriftBooks ® logo are registered trademarks of Thrift Books Global, LLC
